Intern Lumina U2
A Multi-Codebook Diffusion Large Language Model for Omni-Visual Understanding and Image Generation
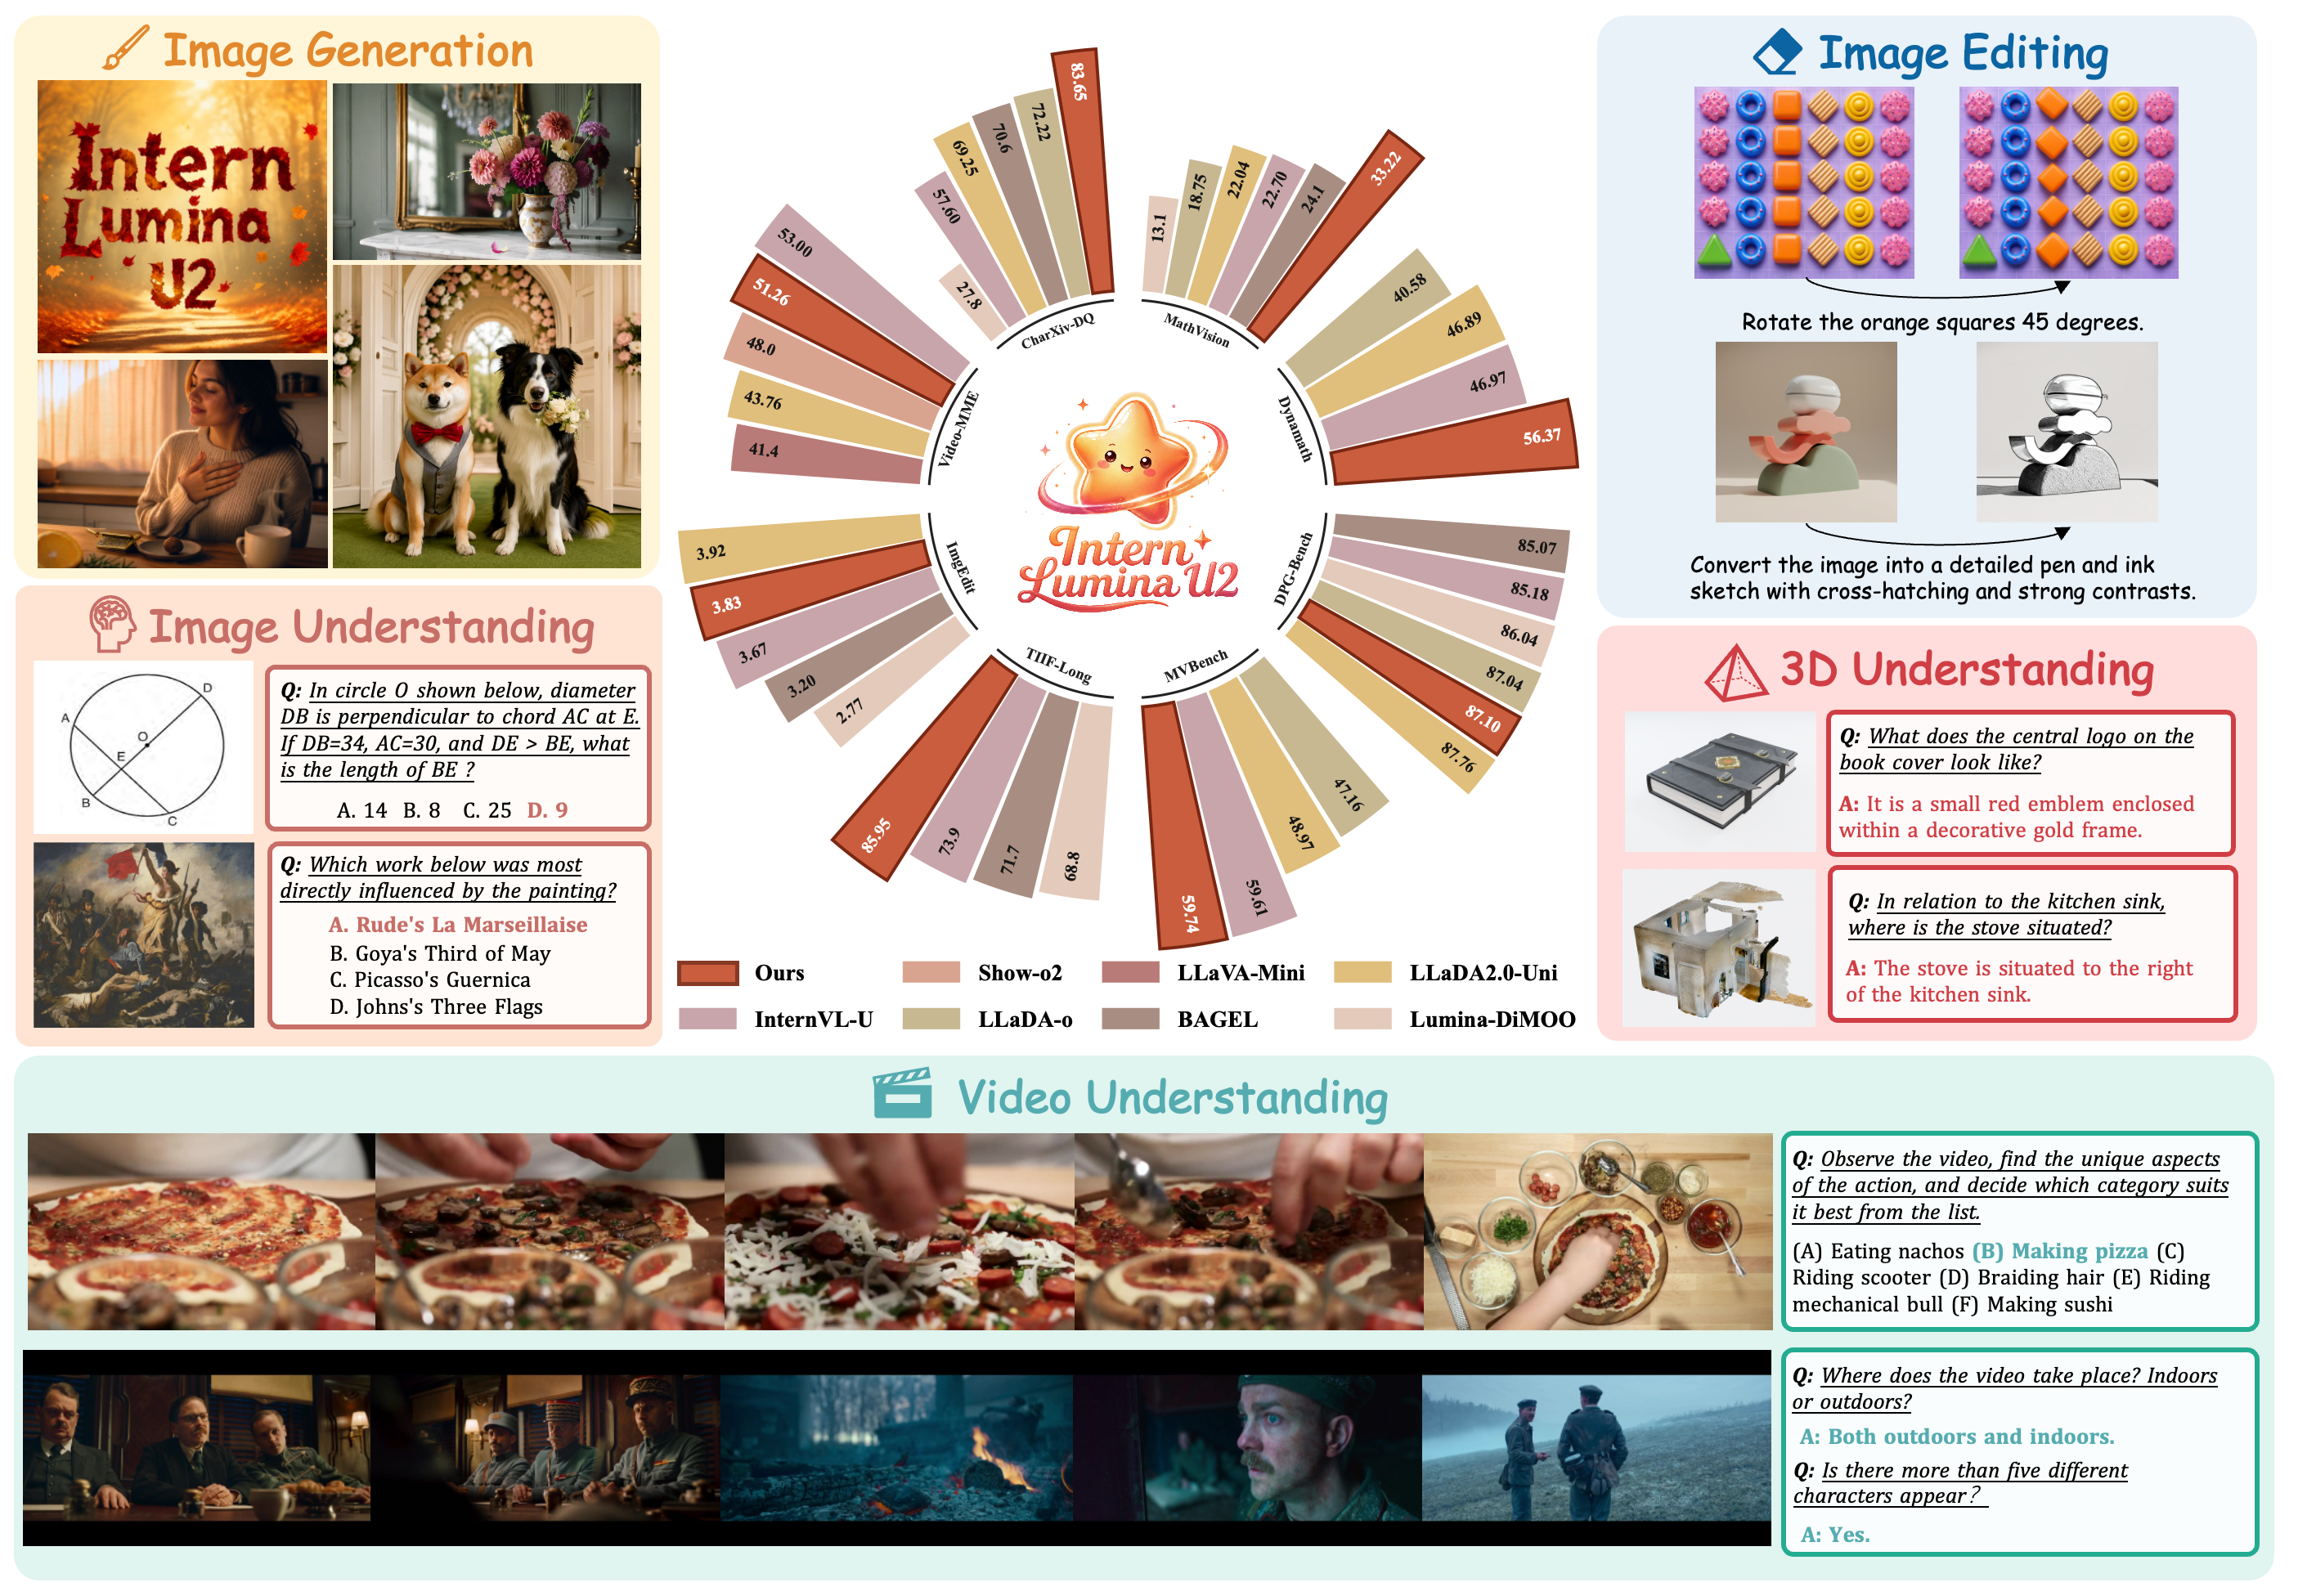
Intern Lumina U2 unifies language, images, video, and 3D for text question answering, image understanding and editing, image generation, video understanding, and 3D understanding.
Experimental Results
| Task family | Benchmark | InternVL-U | LLaDA2.0-Uni | LLaDA-o | Intern Lumina U2 |
|---|---|---|---|---|---|
| Documents and charts | |||||
| Document & chart | ChartQA ↑ | 76.6 | 80.1 | 87.9 | 86.2 |
| Document & chart | CharXiv-DQ ↑ | 53.3 | 68.4 | 69.8 | 85.9 |
| Perception and hallucination | |||||
| Perception | HallusionBench ↑ | 44.8 | 50.2 | 47.4 | 64.6 |
| Perception | MME-C ↑ | 279 | 587 | 527 | 667 |
| Perception | RealWorldQA ↑ | 56.4 | 66.7 | 60.8 | 62.9 |
| Knowledge and mathematical reasoning | |||||
| Knowledge | MMMU ↑ | 54.7 | 50.1 | 44.9 | 52.2 |
| Knowledge | MMMU-Pro ↑ | 20.8 | 34.0 | 28.3 | 38.5 |
| Math reasoning | MathVista ↑ | 55.8 | 68.1 | 66.1 | 68.0 |
| Math reasoning | MathVision ↑ | 22.1 | 26.7 | 15.7 | 36.5 |
| Math reasoning | DynaMath ↑ | 46.97 | 46.89 | 40.58 | 63.6 |
| Generation and editing | |||||
| Image generation | GenEval (0–100) ↑ | 85 | 89 | 86 | 89 |
| Image generation | DPG-Bench ↑ | 85.18 | 87.76 | 87.04 | 87.79 |
| Image generation | TIIF (long) ↑ | 73.9 | — | — | 87.1 |
| Image generation | WISE ↑ | 0.46 | 0.68 | — | 0.56 |
| Image editing | ImgEdit (1–5) ↑ | 3.67 | 3.92 | — | 3.82 |
| Video understanding | |||||
| Compared against | LLaVA-Mini | VideoLLaMA2-7B | LLaDA-V | Intern Lumina U2 | |
| Video | Video-MME ↑ | — | 46.6 | 56.1 | 52.6 |
| Video | MLVU ↑ | 42.8 | — | 59.5 | 62.1 |
| Video | MVBench ↑ | 44.5 | 54.6 | — | 61.8 |
| 3D understanding | |||||
| Compared against | PointLLM-7B | ShapeLLM-7B | — | Intern Lumina U2 | |
| 3D | 3D MM-Vet (total) ↑ | 41.2 | 47.4 | — | 50.5 |
Scores are the released Ascend-trained checkpoint; baseline numbers are taken from the tech report. GenEval is on a 0–100 scale. Video and 3D are compared against specialist models, named in the table where they apply. Video-MME is without subtitles and MLVU is m-avg. A dash means the model does not report that benchmark; Video-LLaVA-7B (Video-MME 39.9, MVBench 43.1) is in the report but does not fit the three baseline columns here.
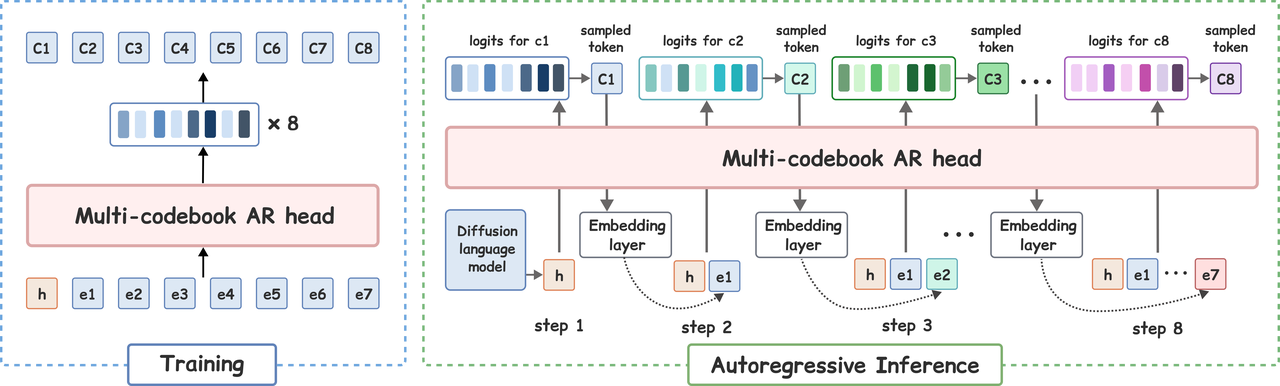
Method.
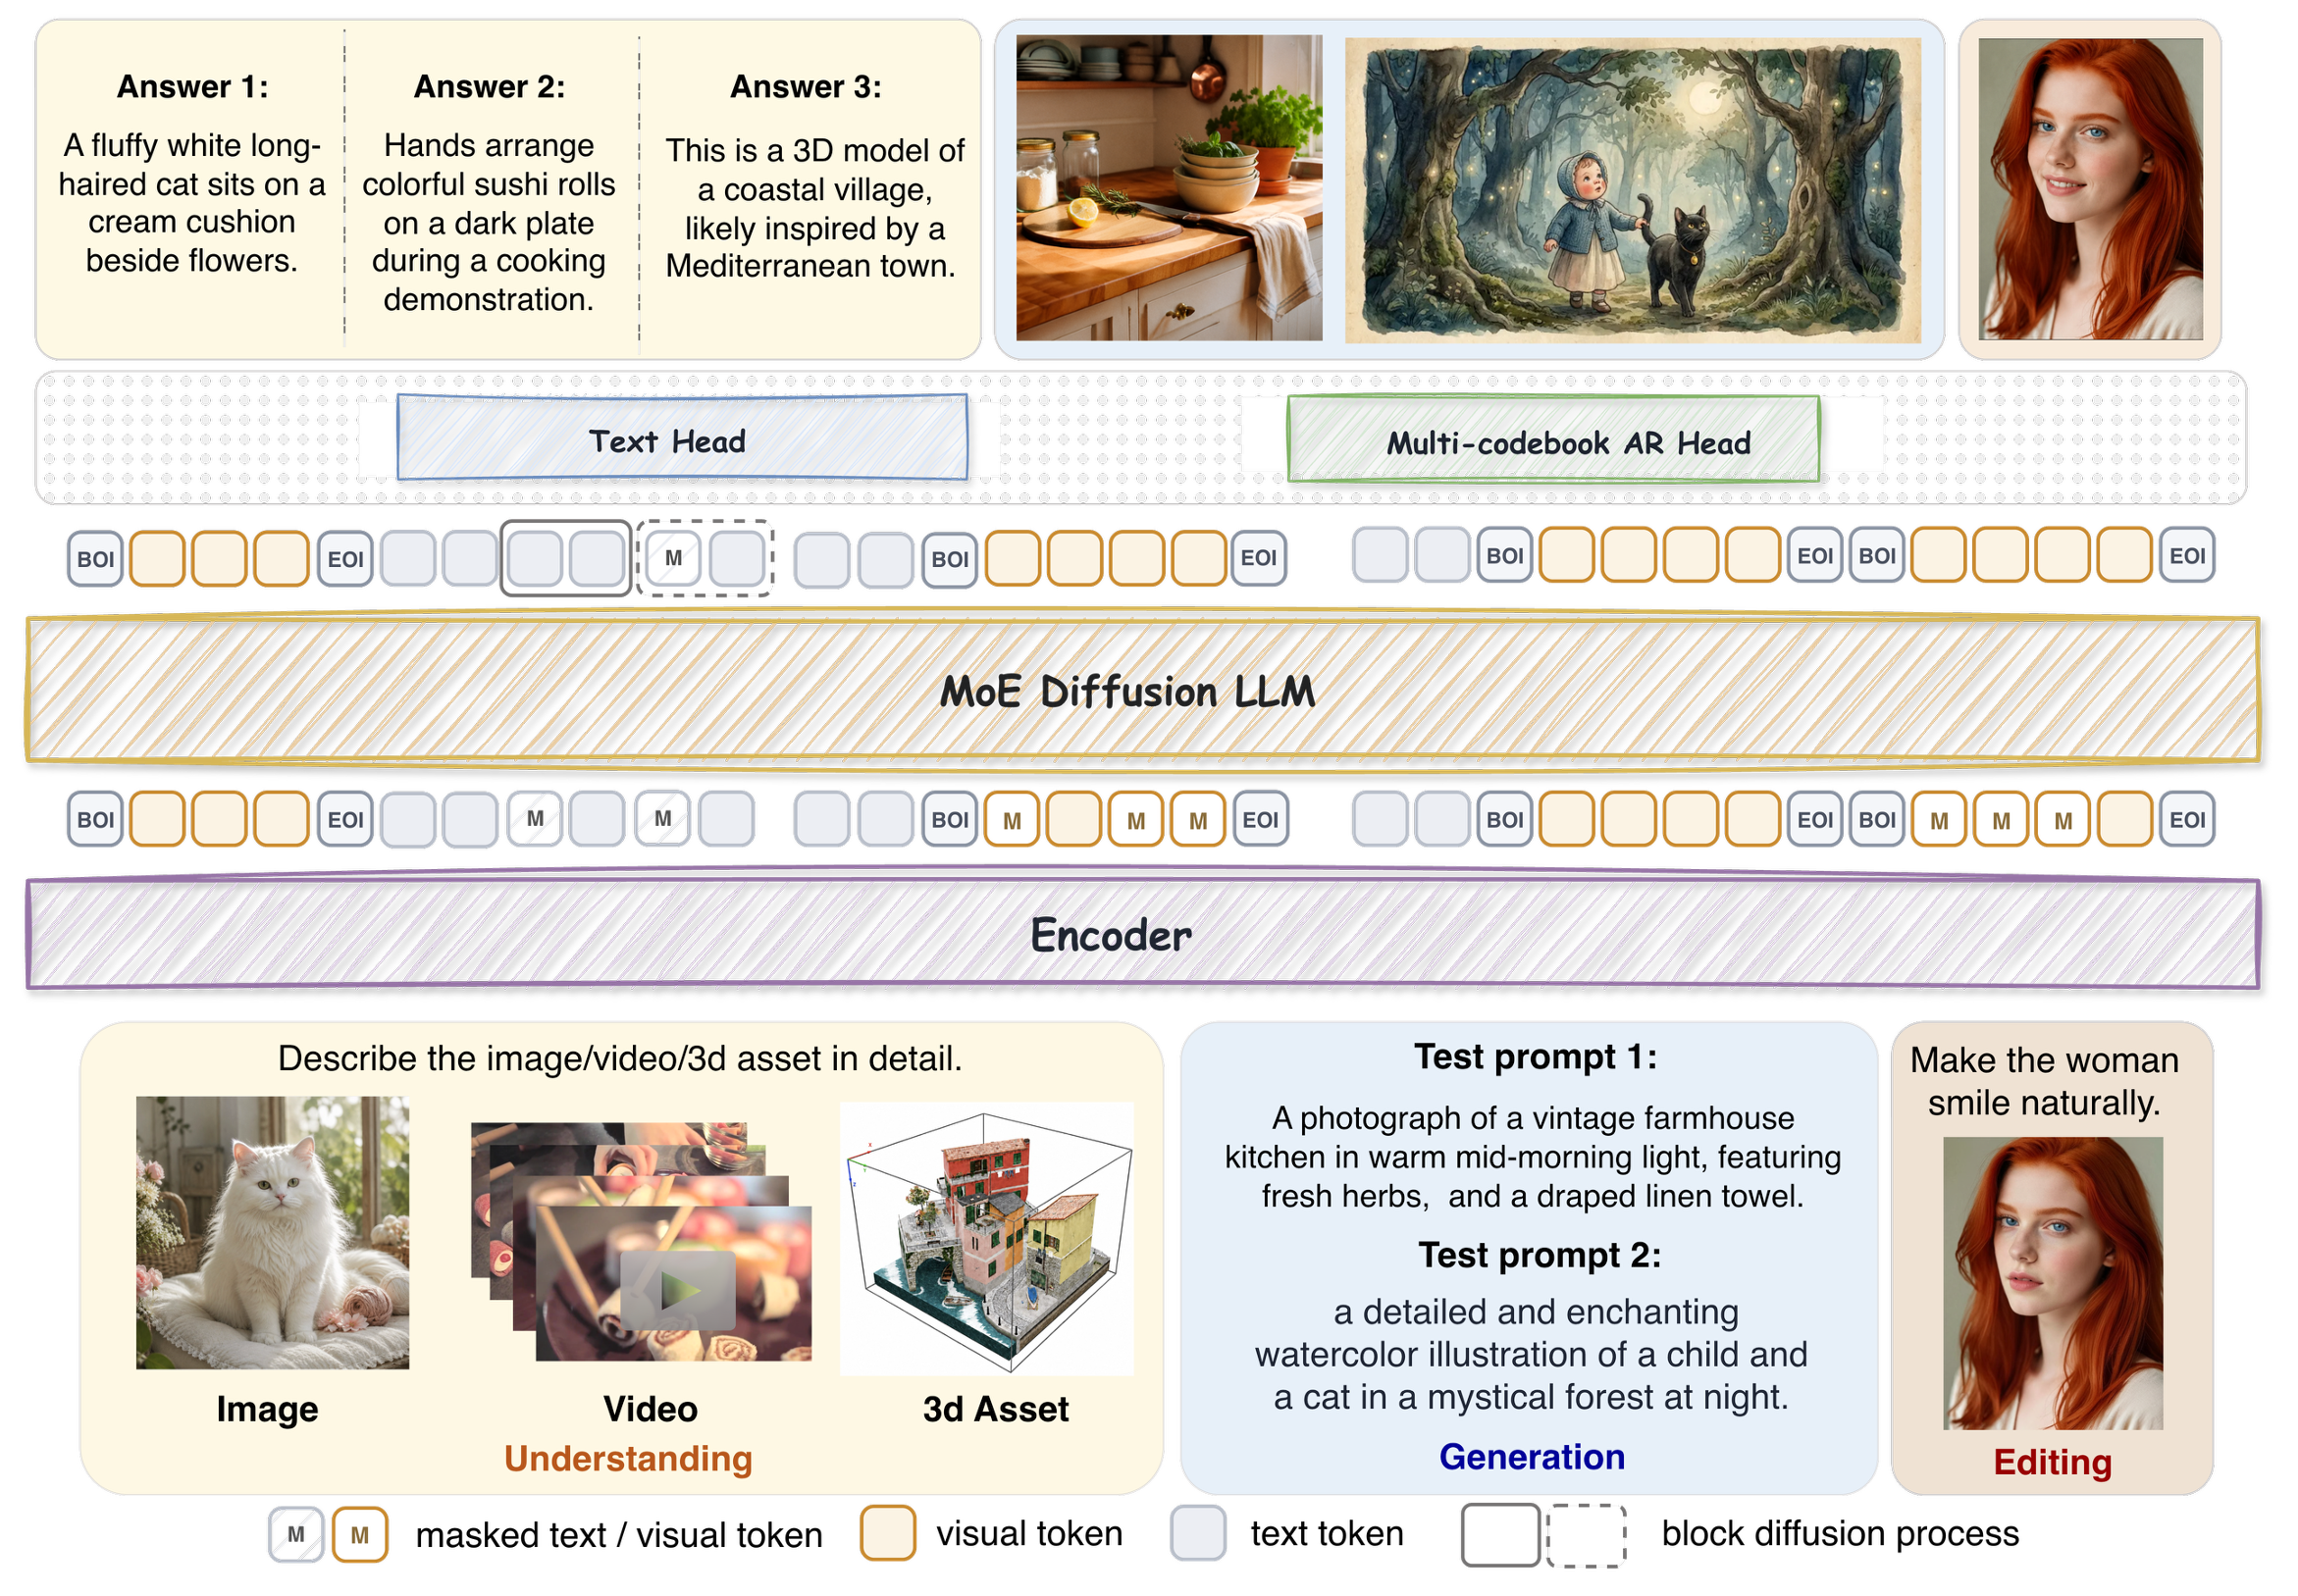
A unified architecture
for omni-visual tasks.
Discrete VQ levels for visual tokens.
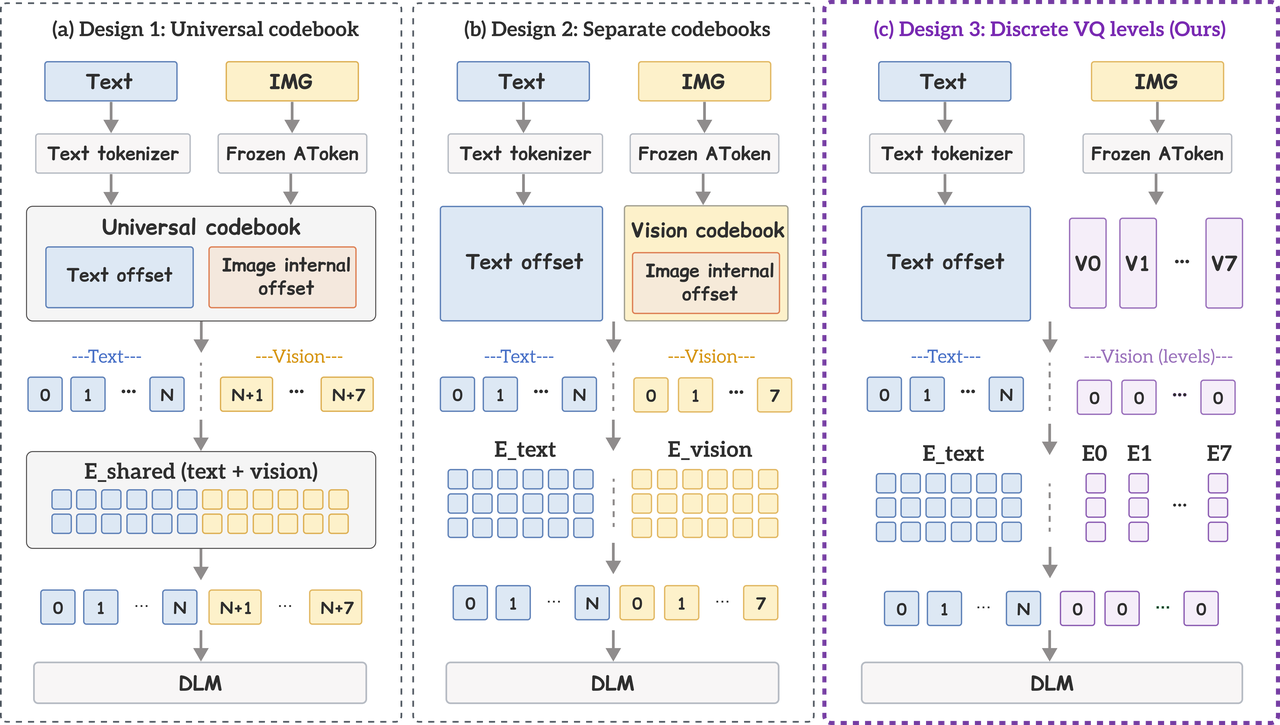
Parallel positions, sequential codebooks.
Demo Examples.
Text-to-Image Generation
Image editing
Image understanding
3D understanding
Video understanding
Resources
@article{internluminau2,
  title   = {Intern Lumina U2: A Multi-Codebook Diffusion Large Language Model for
             Omni-Visual Understanding and Image Generation},
  author  = {{Intern Lumina U2 Team, Shanghai AI Laboratory}},
  journal = {arXiv preprint arXiv:2610.20818},
  year    = {2026}
}